Proactive Agent with Situation Awareness
Proactive agents that maintain situation awareness and adapt their plans as multi-agent environments and other decision-makers change.
I am a PhD student in Electrical Engineering & Computer Science at the University of Southern California, working in the Center of Autonomy & Artificial Intelligence. I am advised by Rahul Jain.
My research studies AI agents that learn and adapt after deployment, connecting LLM post-training, multi-agent game theory, test-time adaptation, and systems optimization. I currently work with Meta Superintelligence Lab (FAIR), after research roles at Microsoft Research and Samsung Research America.
Previously, I studied at the MIT Operations Research Center with Dimitris Bertsimas. At UC Berkeley, I was the first student in the university's history to complete a quadruple major in Electrical Engineering & Computer Sciences, Statistics, Pure Mathematics, and Data Science. I worked with James Demmel, Saul Perlmutter, and Jiahao Yao.
My research focuses on adaptive intelligence: proactive AI agents and language models that continue to learn, anticipate, reason, and coordinate after deployment. The goal is to make adaptation persistent—new capabilities should be acquired at test time, retained across long contexts, and improved through interaction without sacrificing stability or efficiency.
Across LLM post-training, multi-agent game theory, test-time adaptation, and systems optimization, I pursue one question: how can an AI system keep getting better after it enters the world?
Proactive agents that maintain situation awareness and adapt their plans as multi-agent environments and other decision-makers change.
On-policy distillation from black-box teachers using forward-KL objectives to improve reasoning while keeping training aligned with the student's evolving behavior.
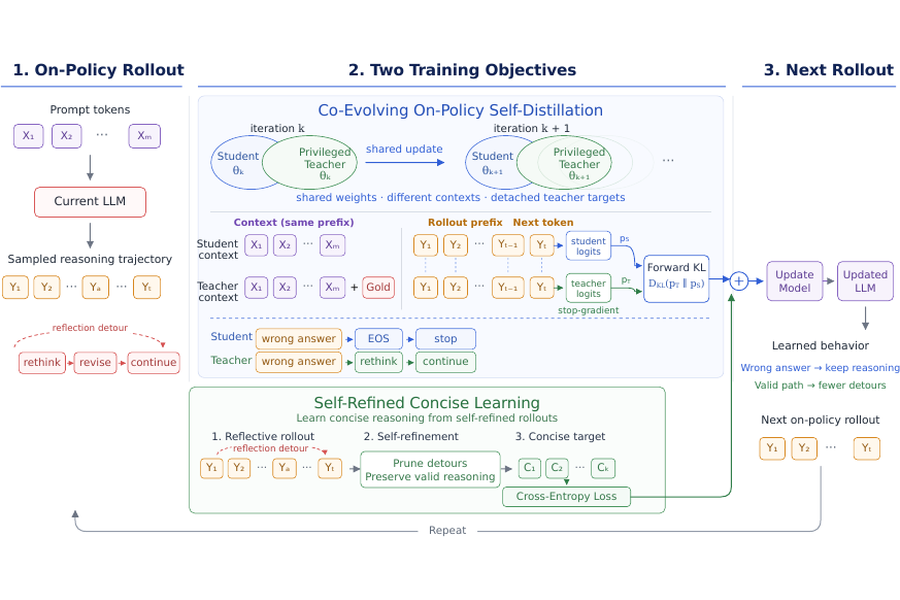
A recursive framework in which a privileged teacher co-evolves with the student, combining dynamic co-evolution with concise self-refinement for stronger mathematical reasoning.
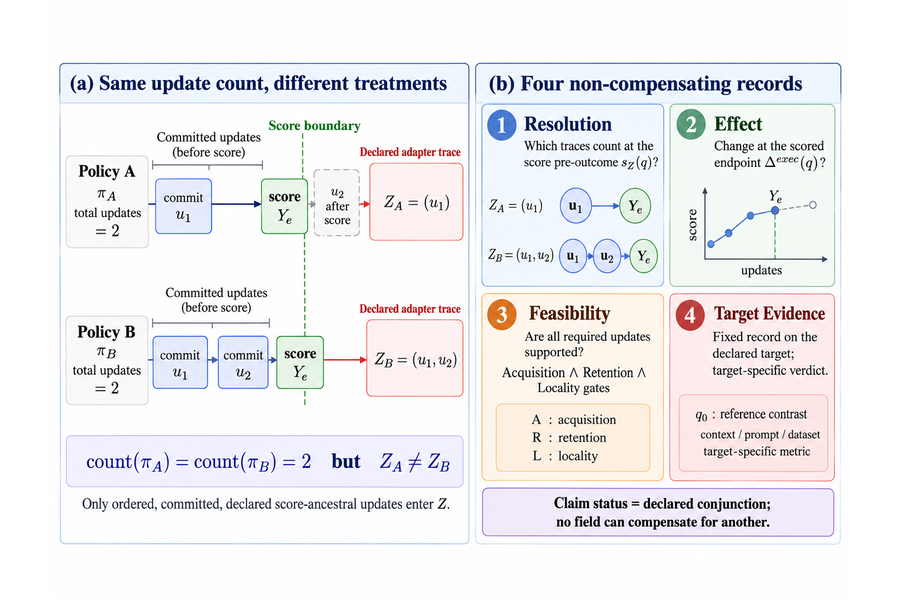
An evaluation framework that records update histories and separately measures acquisition, retention, locality, and generalization in models that learn at test time.
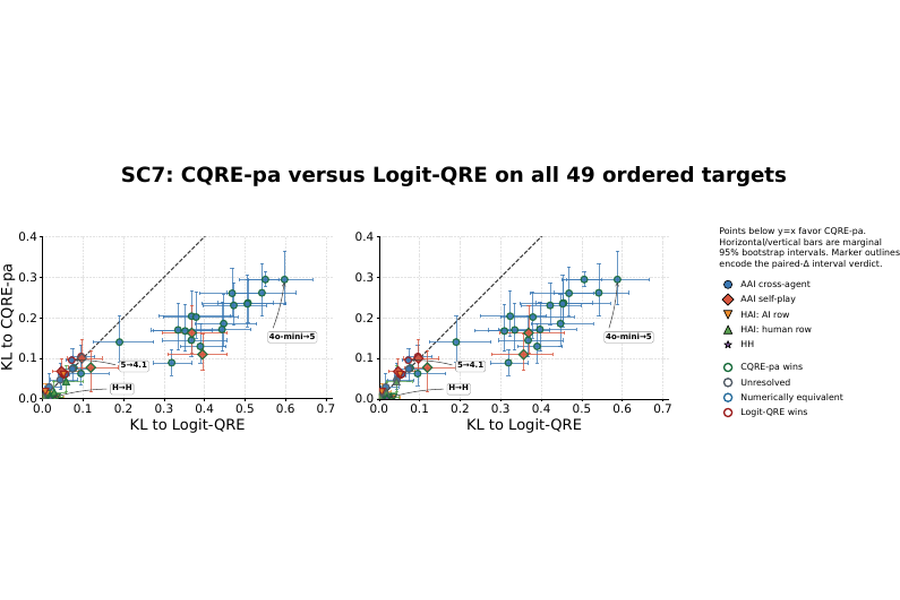
An equilibrium concept combining correlated and quantal response equilibria to model mixed human-AI strategic play, with existence, computation, and empirical results.
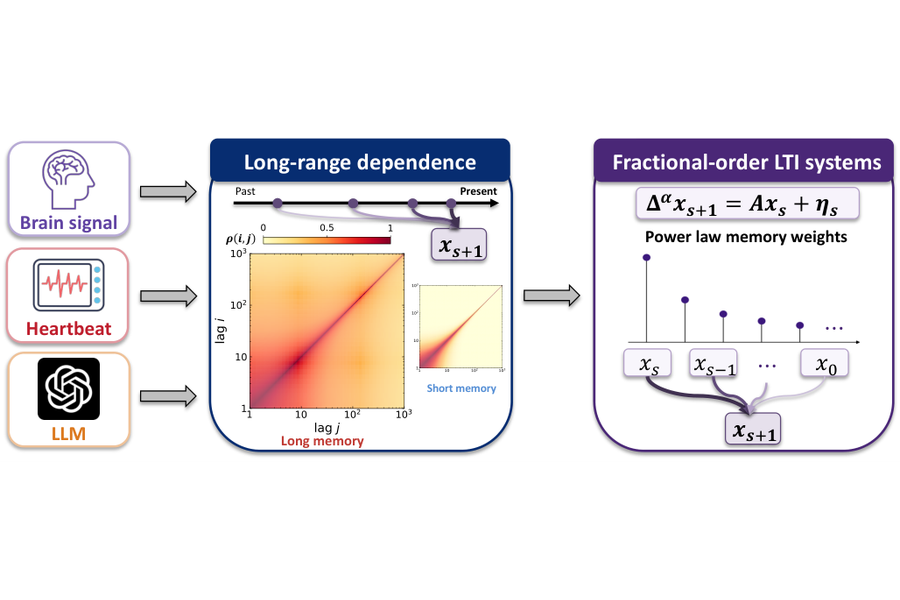
System identification with long-range memory and a practical estimator with non-asymptotic guarantees for learning fractional-order dynamics from one trajectory.
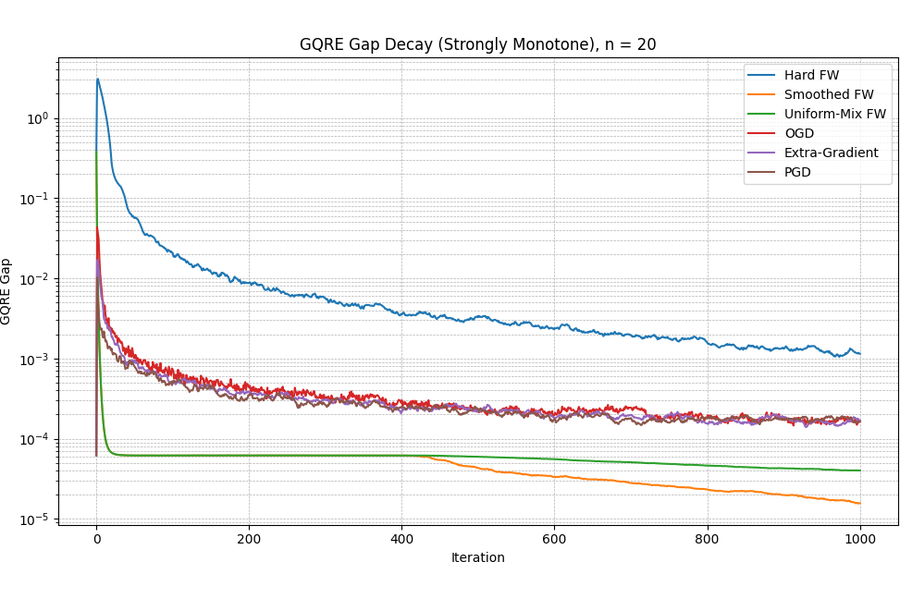
Existence results for generalized quantal response equilibria and a decentralized no-regret learning algorithm using noisy bandit feedback.
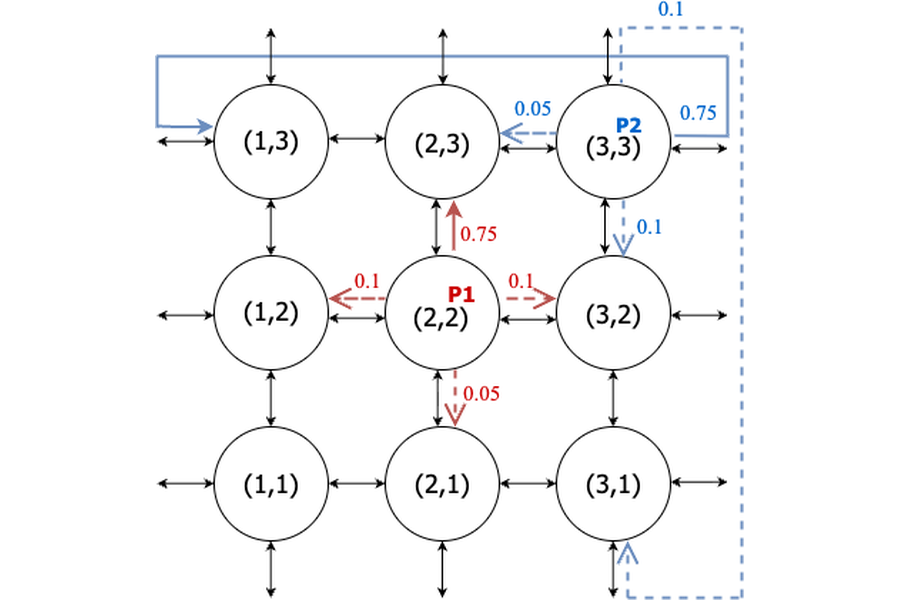
Posterior sampling in unknown finite-horizon zero-sum Markov games, with regret guarantees for symmetric learning and arbitrary opponents.
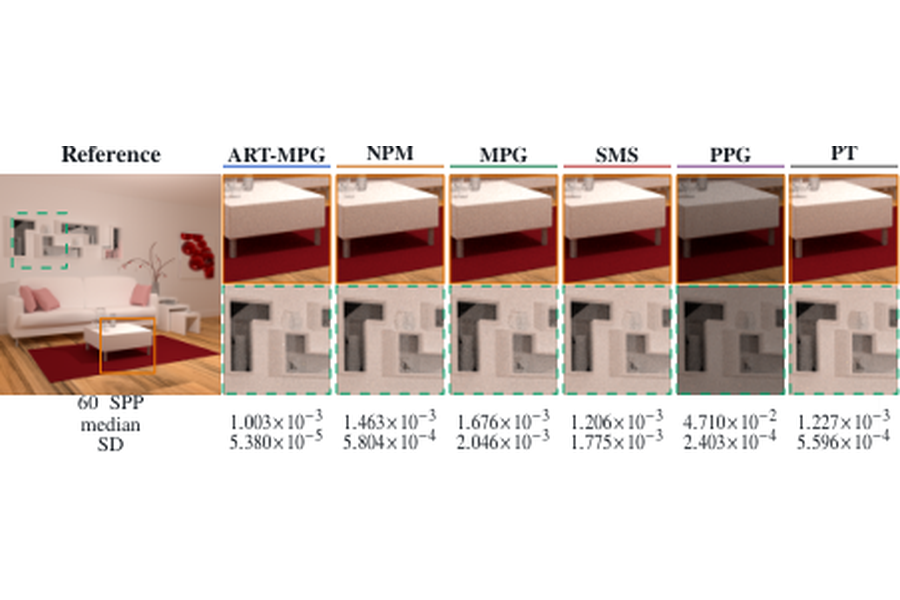
Topology-conditioned neural sampling for specular light transport, improving rendering error and stability across fourteen scenes.
A residual-stability framework for acting against imperfect opponent models, using prediction errors to correct behavior without destabilizing the learning loop.
A hierarchical approach to test-time adaptation that coordinates fast local updates, working memory, and slower model changes across long contexts.
A cooperative-game formulation for populations of self-evolving agents whose policies and shared knowledge adapt under bounded context.
Preference optimization for strategic multi-agent reasoning, aligning language-model policies through comparisons shaped by interacting opponents and collaborators.
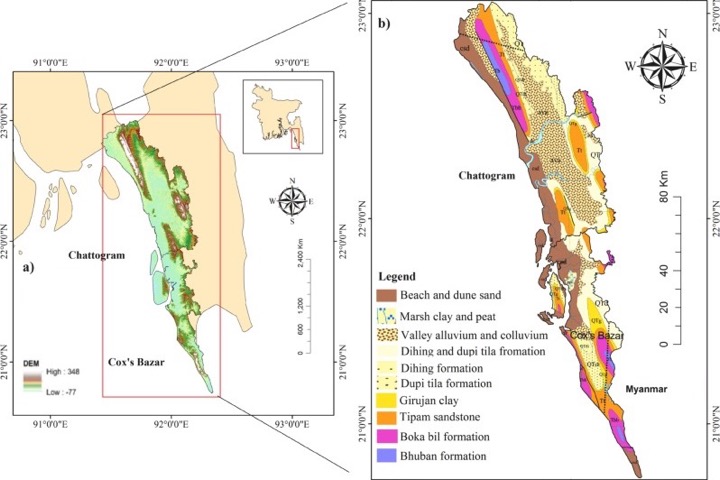
An automated remote-sensing workflow for extracting forty years of shoreline positions and quantifying erosion and accretion along Bangladesh's southeast coast.
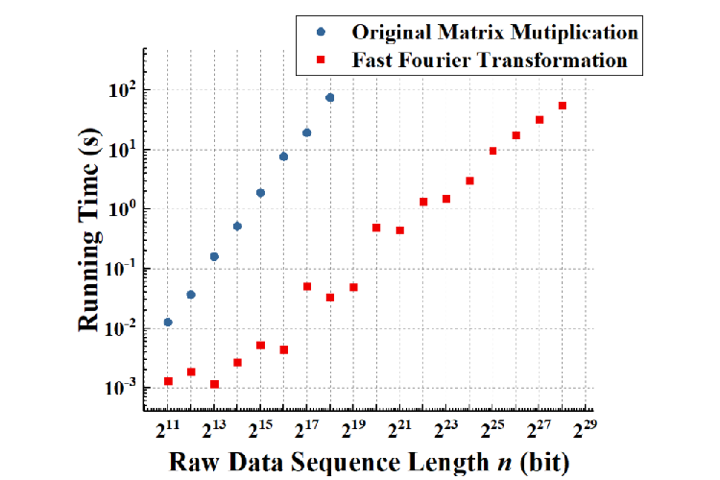
Improves min-entropy evaluation for laser phase-noise generators and accelerates Toeplitz-matrix post-processing with fast Fourier transforms.
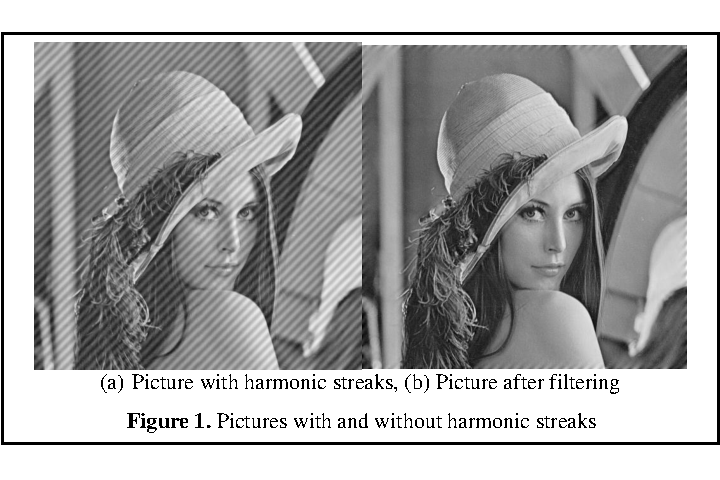
Detects straight periodic streak artifacts through their frequency-domain structure and removes them while preserving the underlying image.
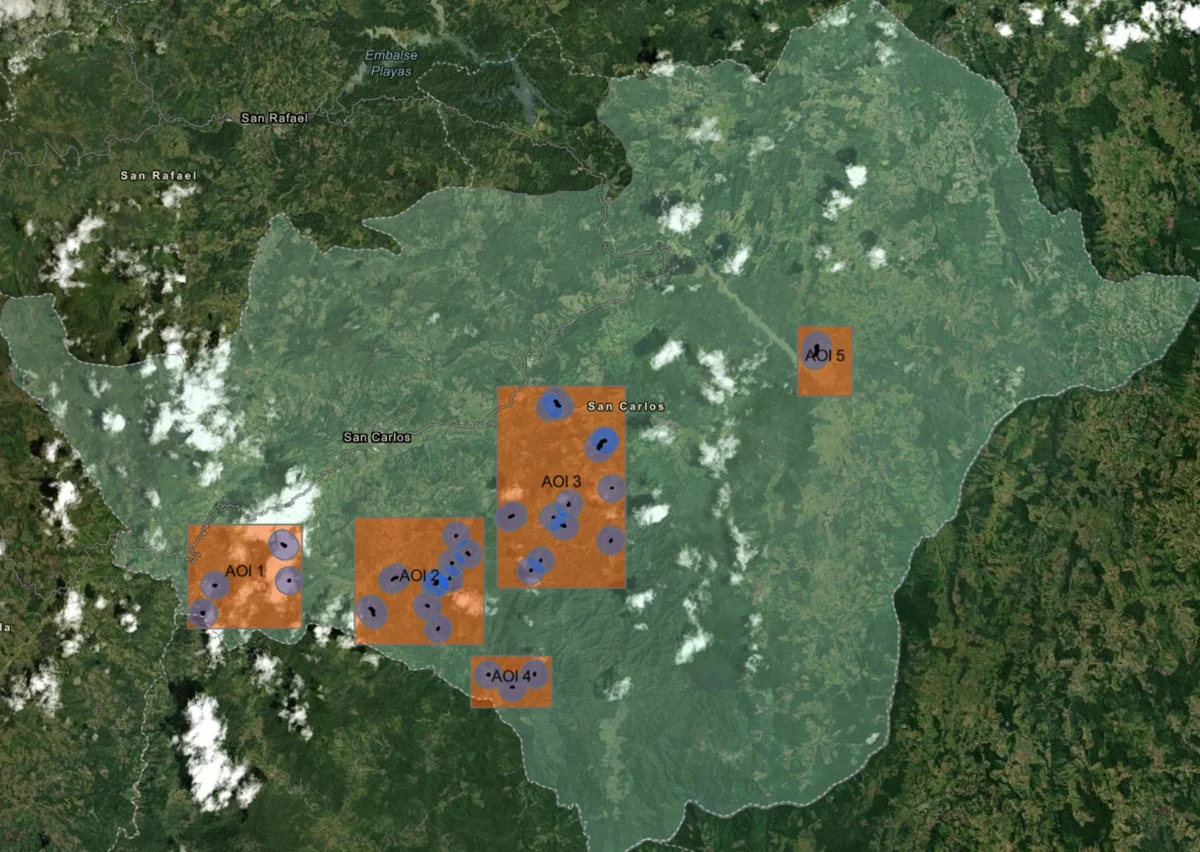
Machine-learning analysis of pre- and post-clearance satellite imagery to identify buildings, roads, and land cover and support evaluation of mine-action interventions.
Researching test-time training, model plasticity, situation-aware proactive agents in changing multi-agent environments, recursive self-improvement, on-policy distillation with black-box teachers, and efficient KV-cache architectures.
Mentors: Mark Ibrahim, Hamed Firooz, Rui Liu, Luke Simon, Yuchen Lu, and Chongyang Bai
Developed learning frameworks for populations of self-evolving AI agents while studying systems optimization for heterogeneous AI infrastructure.
Mentors: Ricardo Bianchini, Rodrigo Fonseca, Haoran Qiu, Fiodar Kazhamiaka, and Alok Kumbhare
Built agentic systems for reducing hallucinations and studied preference-based post-training, evaluation, and multi-agent reasoning.
Mentor: Li Li
Developed multi-agent reinforcement learning and post-training alignment methods, applying game theory to language-model post-training, human-AI strategic play, and multi-objective preference optimization.
Advisor: Rahul Jain
Built personalized AI systems and post-trained language models using interactions from more than 100 users and over 10,000 documents across long contexts and time horizons.
Advisor: Tianyi Peng
Researched data-specific training and evaluation metrics for deep learning in investment applications.
Developed optimization algorithms for multi-agent and counterfactual learning, including polynomial-time approximation methods for difficult optimization and online-learning problems.
Advisor: Dimitris Bertsimas
Researched model compression, routing for federated learning, and approximation algorithms for difficult optimization and online-learning problems.
Advisor: James Demmel
Master's degrees earned en route to the PhD: Computer Science and Pure Mathematics.
Advisor: Rahul Jain
Advisor: Dimitris Bertsimas
Advisors: James Demmel and Saul Perlmutter
zhaozeha [at] usc [dot] edu · zehao_zhao [at] berkeley [dot] edu